Key Info
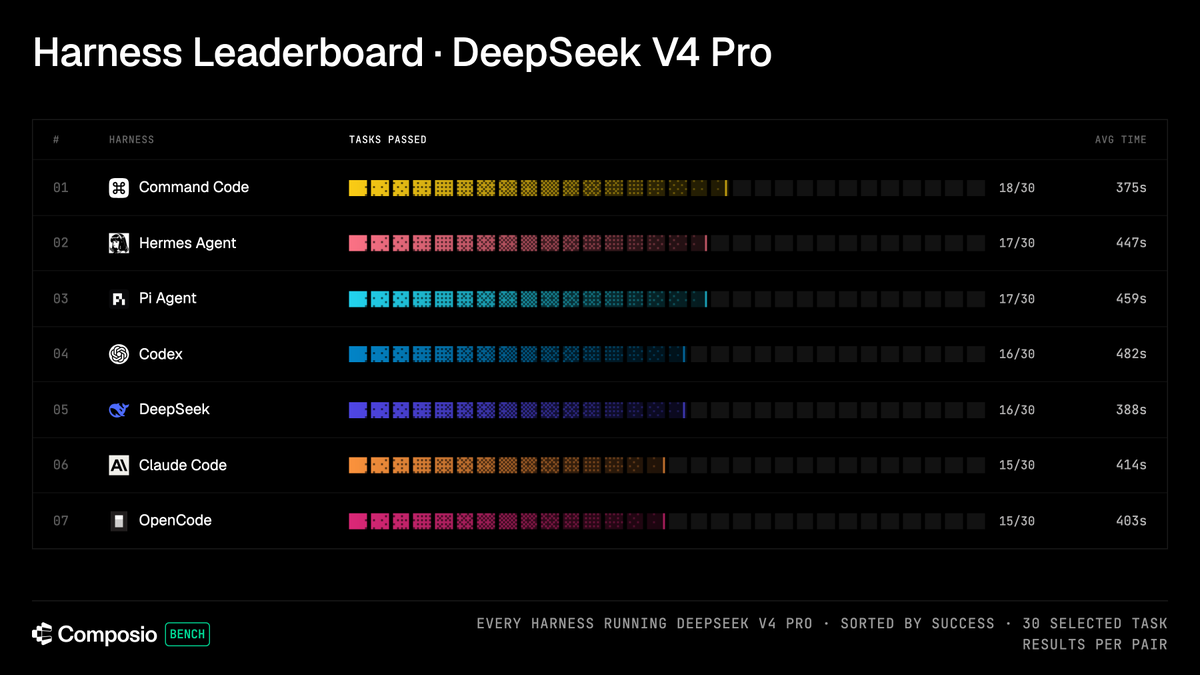
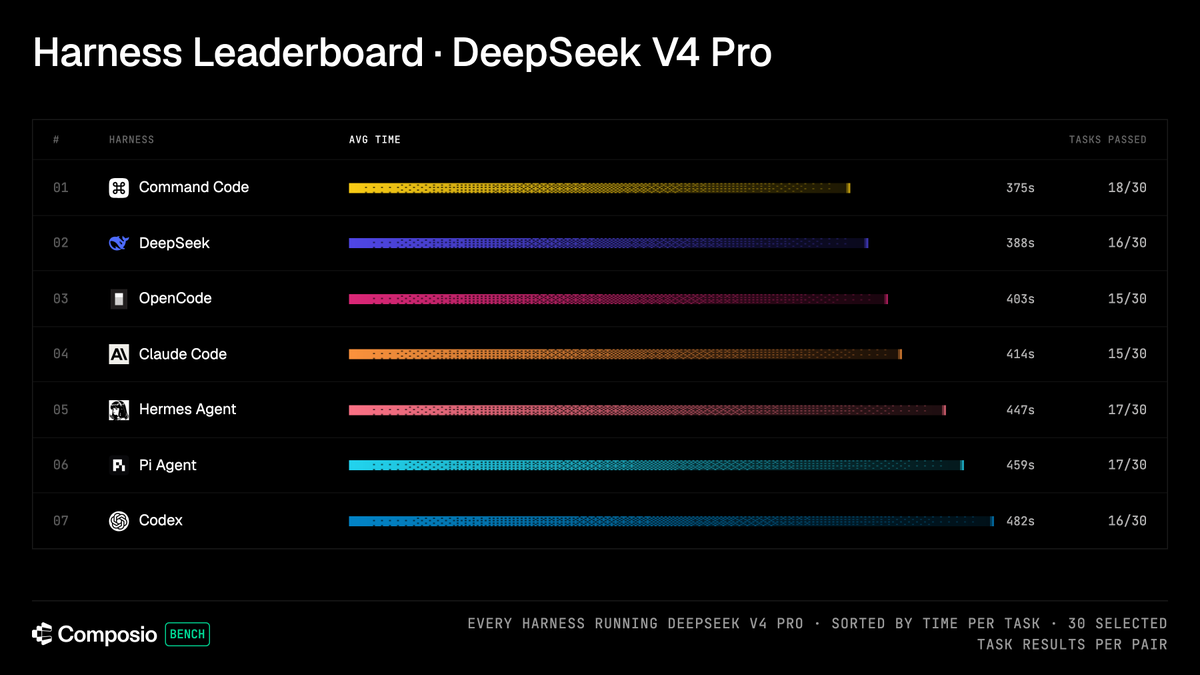
Command Code topped Composio's benchmark on open models like DeepSeek, solving 18/30 tasks with the fastest average time of 375 seconds and beating DeepSeek's own harness. In a separate Composio run with GPT-6 Astra across six agent harnesses on 29 tasks, most harnesses succeeded at similar rates, but failures used 3–5x more tokens depending on the harness.
Highlights
- Most accurate on open models: Command Code solved 18/30 tasks, leading the field.
- Fastest execution: Averaged 375 seconds per task, beating other harnesses on speed.
- Outperformed DeepSeek's own setup: The result put Command Code ahead of DeepSeek's native harness.
- Token efficiency matters: In Composio's broader comparison, harness failures could cost 3–5x more tokens, making efficiency a key differentiator.