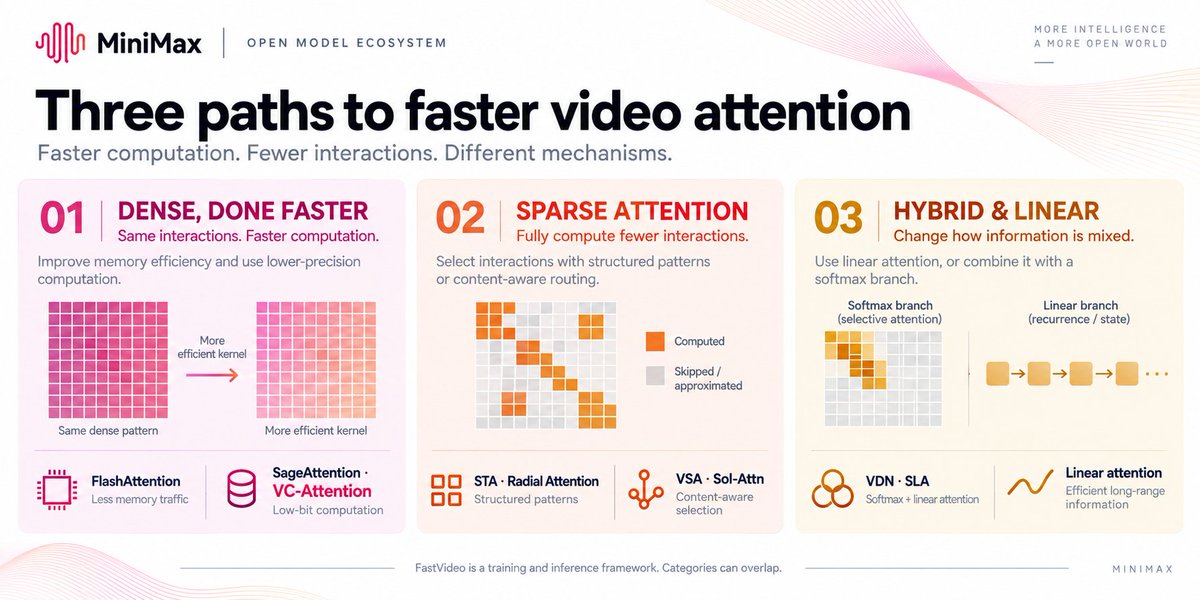
Three paths to faster video attention: compute the same interactions more efficiently, compute fewer in full, or change how information is mixed. Here’s a visual guide. 👇
Thanks to Nunchux AI and collaborators for VC-Attention, bringing training-free low-bit acceleration to MiniMax-H3, with better fidelity than SageAttention2 in the B200 evaluation.
The approach balances speed and fidelity: V-Smooth reduces value quantization error, while ExpCast-FP8 makes softmax faster through approximation.
Excited to see the community keep building on H3. Could combining low-bit computation with sparse methods like Sol-Attn push efficiency further? We’re looking forward to seeing that explored.
引用推文
Introducing VC-Attention: fast and accurate low-bit attention without retraining.
On MiniMax-H3, VC-Attention speeds up attention by 1.6× on B200 and 1.5× on B300 over FlashAttention-4, with better fidelity than SageAttention2. It also works with existing sparse attention methods.
Two key innovations:
• V-Smooth reduces value quantization error.
• ExpCast-FP8 speeds up softmax.
Nunchux Attention, our proprietary extension, pushes the speedup to 1.9× on B200 and 1.8× on B300.
Blog: https://t.co/k0wDVujvBB
Technical Report: https://t.co/wMWfga6m73
Joint work by researchers at MIT, CMU, UC Berkeley, Stanford, and NVIDIA.